02 / AI RESEARCH / COMPANY METRICS
AI-led research still includes human supervision
Anthropic reports Claude led 26% of its AI R&D work in August under human supervision, with none fully autonomous. Its prototype index uses Claude to assess internal work; independent verification and comparable cross-lab methods remain unresolved.
Read the source ↗ www.anthropic.com03 / RESEARCH PRACTICE / OPINION
Test predictions against evidence outside the model
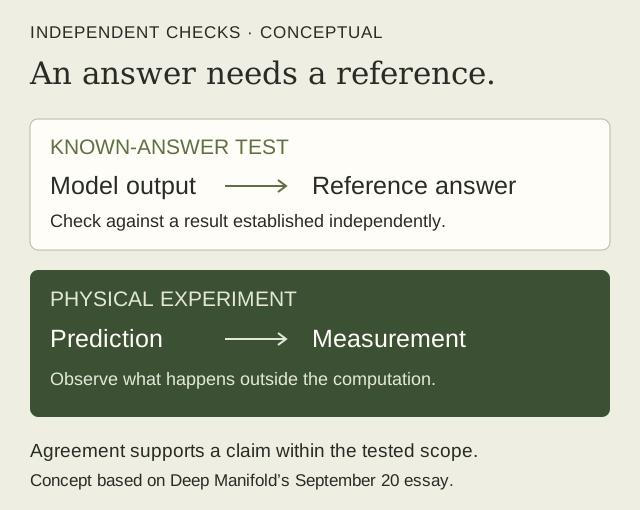 Conceptual illustration of the essay’s distinction. Agreement in a test does not establish reliability in every setting.
Deep Manifold draws a lesson from numerical engineering: known-answer tests check computations, while physical experiments test predictions against independent observations. The essay argues that plausible outputs alone cannot establish reliability in science or engineering.
Read the source ↗ deepmanifold.substack.com