01 / CODING AGENTS / RESEARCH
The same model can come with a different bill
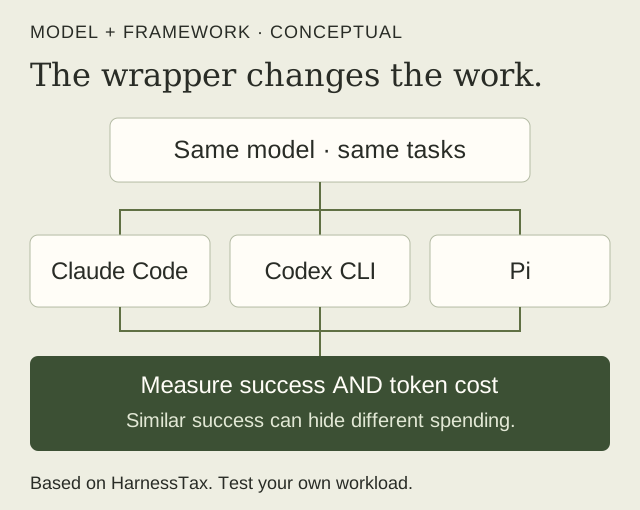 Conceptual illustration based on HarnessTax. Compare both success and token cost; benchmark results do not guarantee savings on your workload.
HarnessTax compares seven models in three coding frameworks on 30 tasks per benchmark. Costs vary substantially despite similar success rates. The authors caution that these public benchmarks may overlap training data; results may differ in real development workflows.
Read the source ↗ harnesstax.github.io02 / OPEN MODELS / ANALYSIS
Open-model competition extends beyond benchmark scores
Nathan Lambert argues that Chinese open-weight models lead on capability and adoption, while U.S. nonprofits lead in fully reproducible releases. His assessment draws on benchmarks, downloads, and platform usage; private deployments remain difficult to measure.
Read the source ↗ www.interconnects.ai